Helping employees find the right item across fragmented enterprise catalogs
I defined the product requirements and measurement strategy for a search service that combined exact-match business logic, semantic retrieval, catalog deduplication, and a simpler purchasing flow.
improvement in search relevance
increase in successful search completion
for 95% of normal-load queries
concurrent users without degradation
The catalog existed. Finding the right item did not.
Employees had to search across multiple procurement catalogs with inconsistent supplier names, descriptions, identifiers, pricing, and delivery data. The same product could appear more than once, while a useful result might be buried because the system treated every attribute equally.
The product challenge was broader than adding a search box. We needed a shared definition of relevance, a way to normalize duplicates across sources, a measurable quality bar, and an experience that moved naturally from discovery to purchase.
Turn business intent into a relevance model
I translated the search problem into a six-stage retrieval strategy. Exact business signals were evaluated first; semantic matching expanded recall only after those high-confidence matches had been exhausted.
Prioritize exact supplier matches when an employee knows the vendor.
Use structured attributes to preserve procurement context.
Capture useful associations not cleanly represented in item titles.
Use item names and descriptions to surface semantic results.
Make ranking logic explicit and testable
The first release weighted relevance as the dominant signal while reserving room for commercial and operational constraints. The model could later incorporate preferred-supplier rules without rebuilding the experience.
80%
10%
10%
Resolve duplicate items before they reach the interface
Catalog search quality depended on how well product records could be reconciled across Coupa and Amazon Business sources. I documented a path that combined identifiers such as CIN and ASIN with normalized supplier, manufacturer, and commodity data.
Disparate catalogs
Different names, descriptions, suppliers, prices, and delivery promises.
Normalize and match
Identifiers, naming standards, heuristics, and machine learning.
One item, many options
Group duplicates while preserving supplier, cost, and delivery choices.
Reduce the distance between query and purchase
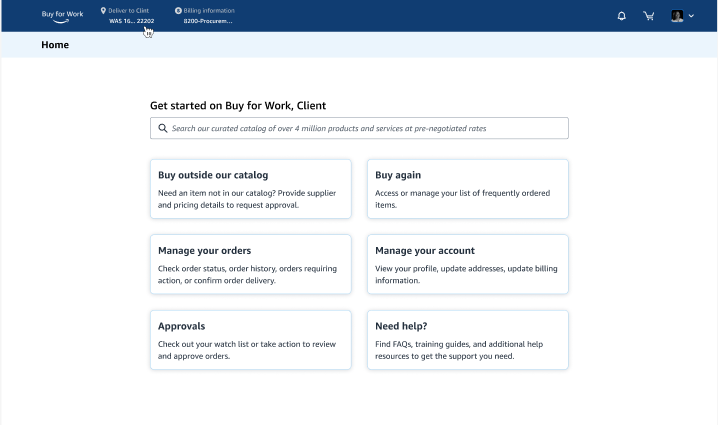
The requirements connected search quality to the full buying task: real-time auto-suggest from item names, nine results per page, multi-select supplier and commodity filters, price sorting, visible product and supplier information, quantity selection, and direct add-to-cart actions.
For failure states, the service paired plain-language error handling with retry actions and “Did you mean” suggestions rather than leaving users at a dead end.
Auto-suggest helps users form a useful query before they submit it.
Nine first-page results balance scanability with meaningful choice.
Supplier, commodity, price, tags, and delivery remain visible.
Retry and “Did you mean” paths turn empty states into progress.
Define quality before launch and behavior after it
I established a two-stage measurement plan. A curated benchmark dataset would validate retrieval and ranking before exposure to users. Once live, behavioral data would show whether relevance translated into useful purchasing decisions.
Benchmark relevance
Precision, recall, MRR, and NDCG@K using real-world queries and expert relevance judgments.
Observe task success
Click-through rate, dwell time, bounce rate, task success, and satisfaction.
The hardest search problems often begin as data problems
The work reinforced that relevance is not only an algorithmic choice. It depends on shared definitions, stable identifiers, clean product attributes, measurable quality thresholds, and an interface that explains enough context for users to trust the result.